d-Matrix announced the general availability of Squadron, a modular, multi‑rack system that aggregates up to 1,024 Corsair XPUs to deliver megawatt‑scale AI inference performance in standard, air‑cooled data‑center environments. The launch, revealed at the OCP Global Summit, marks the company’s shift from a chip‑only supplier to a full‑stack infrastructure vendor, and it is positioned for latency‑critical workloads such as generative coding assistants, autonomous trading, and real‑time cybersecurity.
Squadron in a nutshell
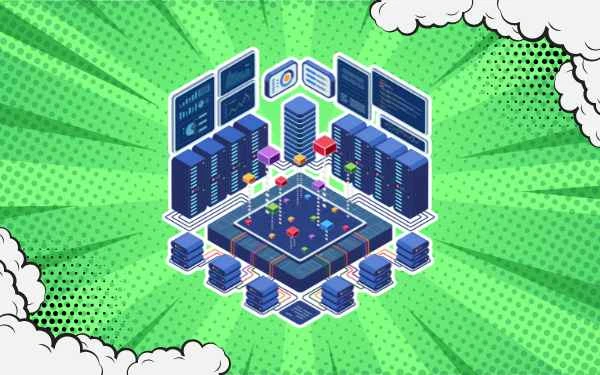
Squadron is a family of rack‑scale compute clusters built around d‑Matrix’s Corsair XPU, a memory‑centric processor that places high‑bandwidth SRAM‑based memory directly on the compute die. Each SquadRack houses eight Corsair servers, and the system can be expanded to 16 racks, yielding a total of 1,024 XPUs and several megawatts of power envelope. The clusters interconnect via d‑Matrix JetStream NICs and are managed by the Aviator software stack, which automates provisioning, health monitoring, and workload scheduling.
How the architecture differs from conventional GPU farms
Traditional inference platforms rely on GPUs that move data between separate memory and compute units, incurring latency and energy penalties. Corsair’s design flips that model: the bulk of the model parameters reside in on‑die memory, allowing the XPU to fetch weights with nanosecond‑scale latency. According to d‑Matrix, this results in up to 2‑3× higher token‑per‑second throughput for large language models when compared with a comparable GPU‑only setup, while consuming roughly half the power per inference.
Disaggregated compute and the AFD breakthrough
During the OCP keynote, CEO Sid Sheth demonstrated “Attention‑FFN Disaggregation” (AFD), a hybrid execution mode where the attention heads run on GPUs and the feed‑forward network (FFN) layers run on Corsair XPUs. In a test with 64 concurrent users, the AFD configuration produced 20,415 tokens per second, translating to 845 tokens per second per user. This is the first publicly shown implementation of AFD on silicon that is commercially available, proving that heterogeneous pipelines can be orchestrated without custom hardware redesign.
Target workloads and early adopters
The performance profile of Squadron makes it attractive for applications where every millisecond counts:
- High‑frequency trading: Sub‑millisecond decision loops benefit from the low‑latency memory access.
- Generative coding assistants: Large code‑completion models require rapid token generation to stay interactive.
- AI‑driven cybersecurity: Real‑time threat detection engines can scan network packets with minimal delay.
- Personal AI agents: Voice or text assistants that run locally in the edge data center can maintain responsiveness without offloading to the public cloud.
Deployment realities
Squadron’s air‑cooled chassis means it can be installed in existing data‑center racks without the extensive plumbing required for liquid‑cooled GPU clusters. However, the system’s power density—multiple megawatts for a full 16‑rack configuration—still demands robust electrical infrastructure and cooling capacity. Organizations must evaluate power‑distribution units, UPS sizing, and facility airflow before scaling beyond a single SquadRack.
Business implications
For enterprises that have already invested heavily in GPU farms, Squadron offers a path to augment existing compute without a complete hardware overhaul. Because the Corsair servers expose standard PCIe and Ethernet interfaces, they can coexist with GPUs in a disaggregated setup, enabling a “best‑of‑both‑worlds” strategy. The general‑availability status also signals that d‑Matrix is moving toward volume production, which could drive down per‑unit costs and make the technology accessible to mid‑size AI labs.
Competitive context
Major cloud providers—Microsoft, Google, and Amazon—continue to expand their GPU‑centric inference offerings, while NVIDIA’s Hopper and H100 GPUs dominate the high‑throughput segment. d‑Matrix’s memory‑centric approach is a differentiated alternative that directly addresses the memory‑bandwidth bottleneck that even the latest GPUs encounter. Competitors such as Graphcore and Cerebras also pursue wafer‑scale or memory‑rich designs, but Squadron’s modular rack‑scale model and reliance on industry‑standard cooling give it a deployment advantage in traditional data‑center footprints.
Limitations and open questions
While the AFD demo showcases impressive token rates, real‑world workloads often involve mixed‑precision tensors, custom kernels, and dynamic model routing that may not map cleanly onto the Corsair architecture. Software tooling is still maturing; developers must adopt the Aviator stack and potentially rewrite parts of their inference pipelines. Moreover, the lack of third‑party benchmark data makes it difficult for buyers to compare Squadron’s performance against established GPU baselines beyond the company’s own numbers.
Looking ahead
d‑Matrix plans to iterate on the Corsair silicon, moving from planar to 3‑D memory‑compute substrates that promise higher density and lower latency. If the company can sustain its roadmap while expanding the ecosystem of compilers and frameworks (e.g., TensorFlow, PyTorch extensions), Squadron could become a cornerstone of next‑generation AI inference, especially for organizations that need to keep inference on‑premise for data‑sovereignty or ultra‑low‑latency reasons.
Market Landscape
The AI inference market is accelerating faster than training. IDC projects the global AI inference hardware market to exceed $30 billion by 2028, driven by the proliferation of generative AI services that require real‑time response. Gartner notes that by 2027, more than two‑thirds of enterprises will run at least one latency‑sensitive inference workload on‑premise or at the edge. This shift creates demand for solutions that combine high compute density with energy efficiency.
Within this context, memory‑centric processors such as d‑Matrix’s Corsair, Graphcore’s IPU, and Cerebras’s Wafer‑Scale Engine aim to alleviate the “memory wall” that limits GPU throughput. NVIDIA remains the market leader, but its roadmap focuses on raw FLOPS and interconnect bandwidth rather than on‑die memory integration. Companies that can deliver modular, air‑cooled systems—like Squadron—are positioned to capture a segment of enterprises that cannot accommodate liquid‑cooling or massive power upgrades.
Adoption is still early. Early pilots reported up to 40 % lower energy per inference compared with GPU baselines, but broader benchmarks are pending. The success of Squadron will hinge on ecosystem support, including compiler optimizations, model‑partitioning tools, and integration with major AI cloud platforms.
Top Insights
- Squadron’s modular design lets organizations start with a single rack and scale to 16 racks without retrofitting liquid‑cooling infrastructure.
- The memory‑centric Corsair XPU reduces data movement latency, delivering up to three‑fold higher token throughput for large language models in early tests.
- Disaggregated compute via AFD shows that hybrid GPU‑XPU pipelines can boost throughput while preserving energy efficiency.
- Power density remains a hurdle; a full 1,024‑XPU deployment requires megawatt‑scale electrical provisioning.
- Industry analysts expect AI inference spend to surpass $30 billion by 2028, positioning memory‑centric solutions as a strategic alternative to GPU‑only farms.
Power Tomorrow’s Intelligence — Build It with TechEdgeAI